a day ago
Analysis: Buterin says local AI can protect privacy without losing speed
Ethereum co-founder Vitalik Buterin argues that local AI can protect your privacy without losing speed
CryptoSlate
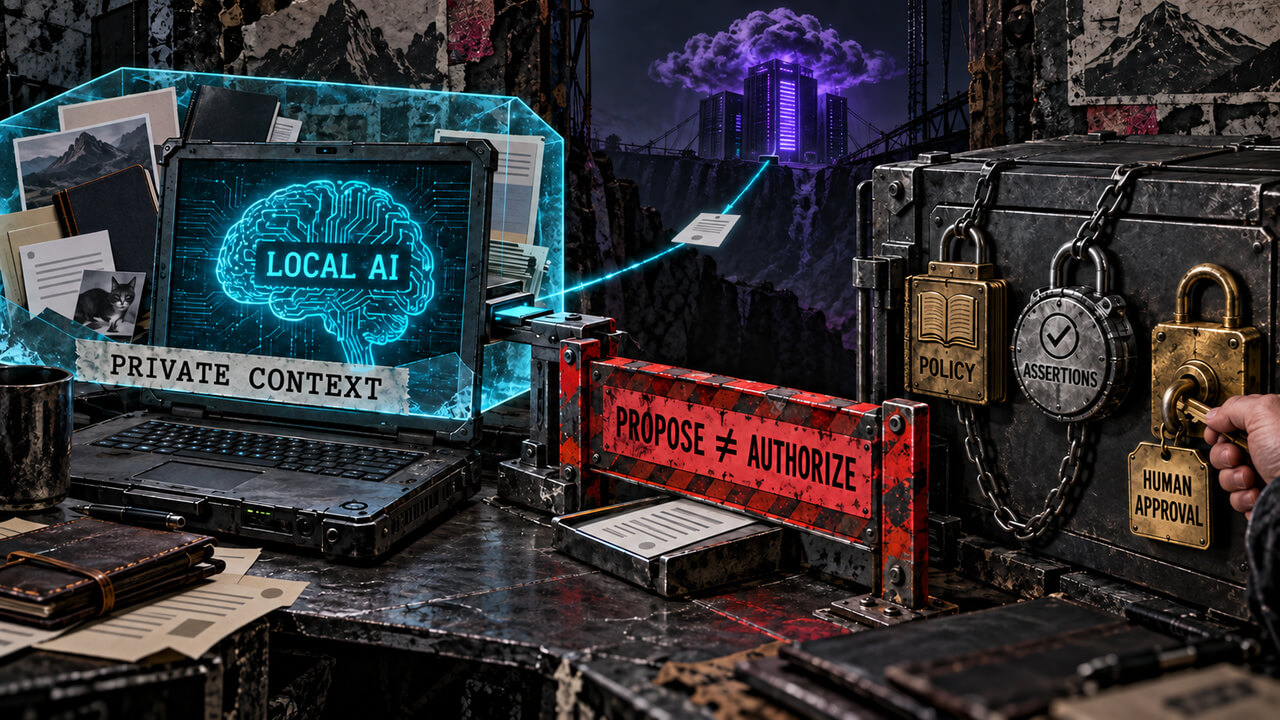
Vitalik Buterin said on Sept. 17 that Qwen 3.8 Flash and recent improvements in llama.cpp had brought local models close to handling a large share of tasks on his Strix Halo laptop. He described a local model coordinating requests to stronger remote systems while withholding the user's full personal context. A benchmark image attached to his post showed 10 workloads, with reported input-processing rates ranging from 109.82 to 373.22 tokens per second and output-generation rates ranging from 18.42 to 33.37 tokens per second. Those figures support a responsiveness claim for one high-end laptop, but they do not establish model judgment, resistance to malicious instructions or transaction authorization. Compared with an April account, Buterin's September assessment gives laptop models a broader role than transcription, summarization and other tightly bounded tasks. In the newer description, a local model can serve as the main interface for more activity and decide when a remote model is needed. The remote service receives only the question or context selected by the local model, rather than every file, message and wallet detail in the user's wider situation. The April and September accounts involved different model generations and tasks, and the September post omitted prompt contents, quantization choices and the full runtime configuration. The article identifies Qwen3.8-Flash-Next as an open-weight multimodal mixture-of-experts model released by Alibaba's Qwen team. Its main model has 125 billion parameters, plus another 51 billion in n-gram embedding tables, while 6 billion parameters are activated per token. The official repository documents local text and vision inference through llama.cpp using quantized GGUF builds. Activating only part of the model for each token lowers the compute burden, but users still need enough memory for the selected build and context. The official materials provide no single hardware minimum that applies across quantization levels and workloads. Qwen's technical report evaluates the base model across 14 benchmarks covering general knowledge, mathematics, science, reasoning, coding and multilingual understanding. The Qwen team reported that Flash-Next beat the larger Qwen3.7-Plus base model on eight tests while using fewer activated parameters and less training compute. Those benchmarks cover capability, efficiency and training stability, not prompt-injection resistance, policy enforcement, wallet authorization or the correctness of autonomous financial actions. An assistant could privately explain a transaction, prepare calldata or suggest a route, while a signer could make an irreversible request that transfers assets or grants another contract permission to move them. Malicious instructions hidden in a website, message or transaction description could still redirect the model's plan. The Ethereum Foundation's second-quarter allocation update listed Steward, a fully local macOS smart-account wallet whose light client and AI assistant are intended to run on-device. That disclosure establishes funding and project scope, but not production deployment, independent audit status or autonomous transaction authority. Buterin's April wallet guidance placed policy outside the language model through a human-confirmation firewall for risky actions, deterministic limits on transaction amounts, calldata and transaction counts, and a human-plus-model 2-of-2 rule. Low-risk automation could remain available within software-defined permissions, such as reading balances, preparing unsigned transactions or operating under tightly capped limits. EIP-7906 remains a draft and proposes post-transaction assertion frames that inspect the final state differences produced by a transaction. An assertion could reject an outcome when it violates a specified condition, such as changing unapproved balances, creating a hidden token approval or touching a protected account. The article notes that an assertion checking too little could create false confidence, so wallet validation logic must require the intended assertion frame and the assertion must cover every relevant state change. Local inference and transaction assertions address different parts of the wallet-agent problem. The local model protects context and turns natural-language intent into a proposed action, deterministic permissions restrict recipients, contracts, value and frequency, assertions inspect final state changes, and human confirmation remains a second factor for risky actions. The laptop result makes the local model layer more credible for fast coordination and selective use of remote intelligence, but asset authority remains with controls the model cannot alter and an approval path that keeps the user meaningfully in charge.
This content is an AI-generated summary/analysis for informational purposes only and does not constitute investment advice.